
Union self-serve now supports Google Cloud. Sign up, connect a GKE cluster in your own project, and run training, pipelines, agents, and inference on a durable runtime, with your data, traces, and compute staying inside your perimeter.
When we launched Union self-serve in September, it ran on AWS first. The teams asking for Google Cloud had something in common. They'd already chosen GCP as the place to build their AI factory, so they had the GKE clusters, the GPU and TPU quota, the data in Cloud Storage and BigQuery, and the security review that put all of it inside their own project. What they didn't want was a platform that asked them to move any of that somewhere else before it could be useful.
As of today you can connect a GKE cluster to Union yourself, from the Union UI, without a sales call. This post is about why that matters if you're building on Google Cloud, and what you actually get.

The infra is on GCP. Something still has to coordinate the production line.
"AI factory" has become the industry's word for what everyone is building: accelerators, data, and networking arranged to turn data into models and agents. On Google Cloud, most of that infrastructure is already there. GKE schedules the containers, Cloud Storage holds the data, Artifact Registry holds the images, Vertex AI and Gemini give you models, and TPUs and GPUs give you the compute.
What you don’t quite have yet is the production line, the part that turns a pile of infrastructure into a model that gets retrained every week, an eval suite that runs on every checkpoint, or an agent that finishes a forty-step task reliably. What powers that production line is code, and it breaks constantly in ways that have nothing to do with the code itself. Nodes get preempted, a step runs out of memory on the one batch that's bigger than the rest, and a GPU pool runs dry halfway through a fan-out. The solution brief we wrote with Google Cloud puts infrastructure at about half of all AI workflow failures. When the orchestrator can't see the infrastructure, each of those failures becomes a restart from zero and a person babysitting it.
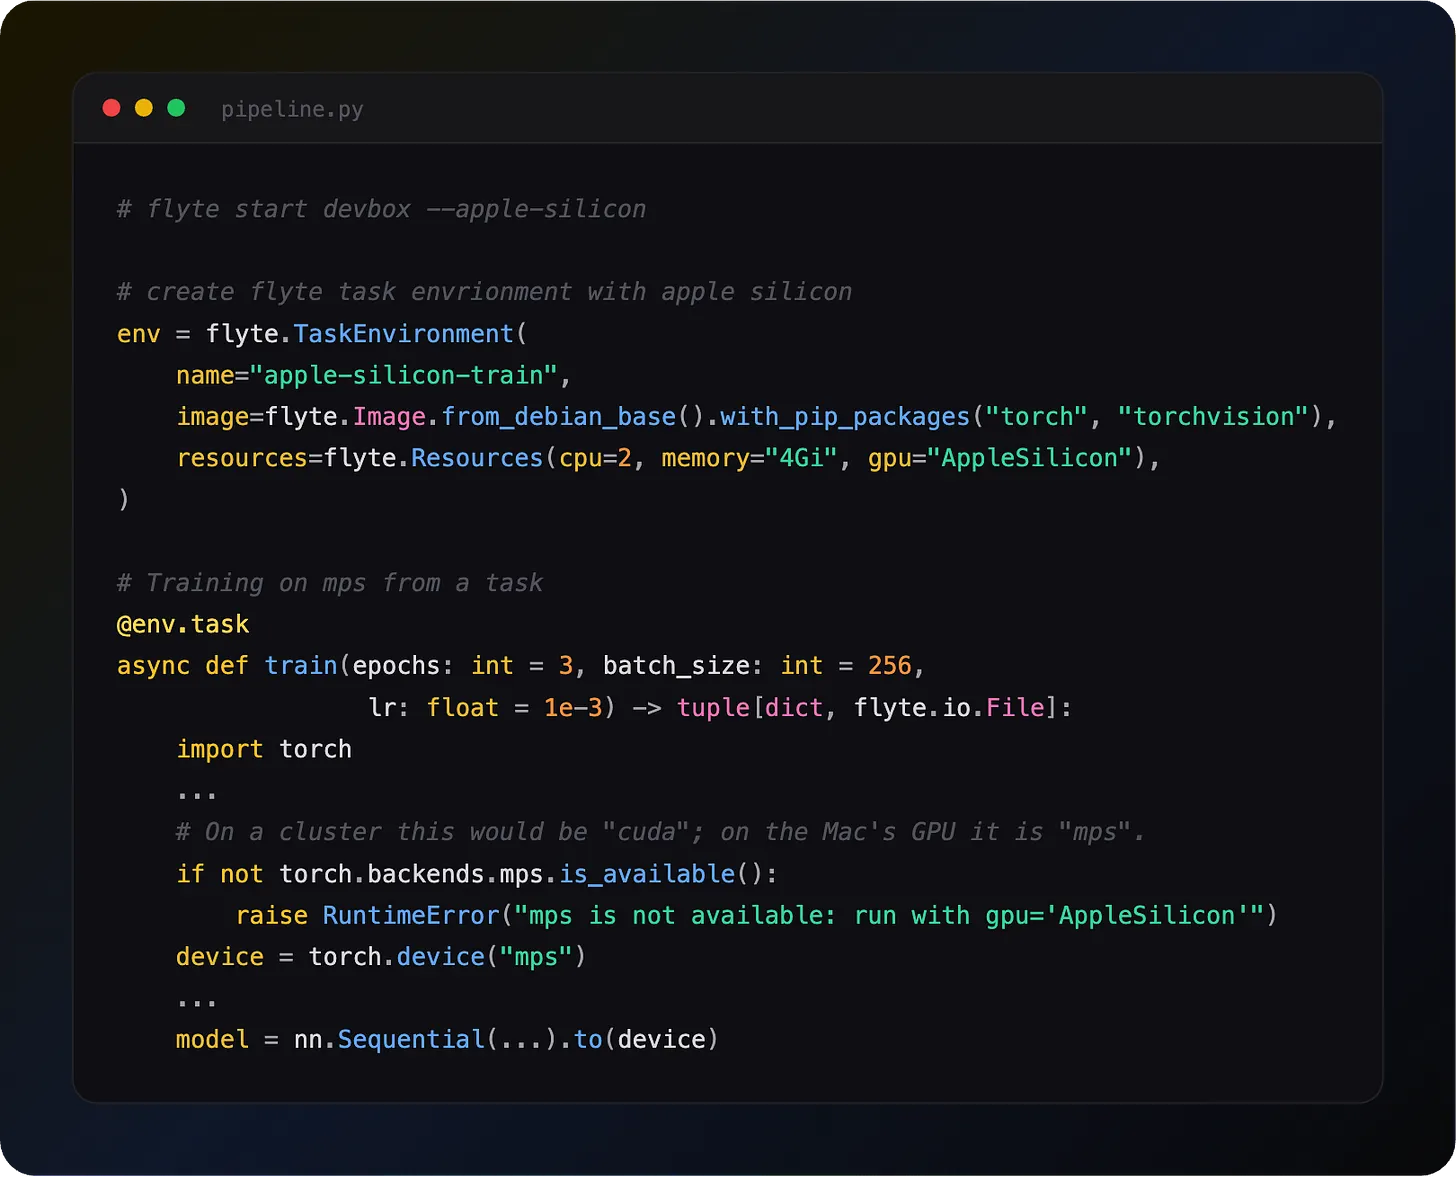
Union runs your AI factory in infrastructure you own. It's built on Flyte 2. You write it in plain Python, and it runs on the GKE cluster you already have.
What "sovereign" means here
To a lot of readers "sovereign AI" means a nation's AI capability, so we'll be specific about how we use it. For us, sovereignty means owning and governing it yourself: the software, the data, the execution traces, the compute choice, and model access.
On Google Cloud, that comes down to where things live:
The Union control plane holds run IDs, state, and references to artifacts, and the bytes stay in your bucket. The UI reads them straight from Cloud Storage with signed URLs, which is why the setup asks you for a CORS rule naming your Union UI's exact origin. The connection runs in one direction. You install an agent into the cluster and it dials out to Union, so you don't open a port, expose an endpoint, or hand over cluster credentials. Nothing dials in.
There's no service-account key file anywhere in that picture. Your task pods act as the task service account through Workload Identity, which can read and write the data plane's bucket, push to its image repository, and read runtime secrets, and that's the whole grant. If you're the platform engineer who has to approve this, the GCP provisioning guide lists every role and binding, so you can read exactly what gets granted before anything is created.
What you get on GKE
Runs that finish
Union keeps workflow and agent state in durable storage rather than on the node doing the work. When a Spot VM gets preempted or a node pool drains, the step that was running picks up where it stopped, and the steps that already succeeded aren't recomputed. A failure at hour eleven of a twelve-hour pipeline costs you the last hour.
Out-of-memory kills arrive in your code as a typed exception, so you can decide what happens next in Python instead of reading a pod event after the fact:
On GKE this pairs well with node auto-provisioning, which the provisioning guide turns on. When the retry asks for 64 GiB, GKE adds a node pool that fits it, and scales that pool back down once it's idle.
Compute you can account for
GPUs and TPUs are the expensive line on the bill, and the waste usually comes from paying twice for the same work: a rerun that recomputes finished steps, a job holding half a cluster while it waits for the rest, or a backfill crowding out production. Union caches task outputs so identical work isn't repeated, gang-schedules multi-node jobs so they're admitted all-or-nothing, and puts work behind queues with priorities and per-team quotas. You get cost and utilization per workload, which means you can charge it back to the team that ran it.

One runtime from data to serving
The same Python that defines a data pipeline defines the training run, the eval, the agent, and the endpoint that serves the model. Steps share typed, versioned artifacts rather than code, so lineage gets recorded as a side effect of running things: which code version, which data, and which container produced each output. For teams in regulated industries, that record is what the audit asks for, and it sits in your project.
Union works with the Google services your teams already use. Tasks read from and write to BigQuery and Cloud Storage, agents call Gemini through Vertex AI, and every LLM and tool call in an agent loop is a checkpointed step, so a crash on turn seven resumes at turn seven.
A portable open core
The runtime is Flyte, open source under the Linux Foundation. If you're running Flyte 2 on GKE today, moving to Union is a configuration change rather than a rewrite. The same is true in the other direction, and we think that's the part that makes the rest of the sovereignty argument hold up.
Getting started on Google Cloud
To run Union on GCP, you need to:
- Create your organization at union.ai/signup and do a tracked run of `hello.py` on your own machine. It shows up in the Union UI with its inputs and outputs before you've touched any cloud permissions.
- Provision the GCP resources. The provisioning guide creates a regional GKE Standard cluster with private nodes, Cloud NAT, Workload Identity, and node auto-provisioning, plus the bucket, the Artifact Registry repository, and the three service accounts, all with `gcloud`. If you already have a cluster that meets the requirements, you can use it instead.
- Connect the cluster. In the Union UI, create a cluster pool with your bucket, project ID, and registry, register the cluster with its two service-account emails, and run the generated install command. The agent connects out, and Union installs the data plane through that connection.
- Run it again on GKE. The same `flyte run hello.py main`, without `--tracked`, now runs on your cluster.
A few things to know going in:
- The cluster has to be GKE Standard, because Union's image builder runs privileged pods, which Autopilot doesn't allow.
- Nodes need 200 GB boot disks, or image builds stay pending.
- The guide grants Secret Manager roles at the project level, because the data plane creates its own secrets and there's nothing narrower to grant them on yet, so we recommend a project dedicated to the data plane.
- Self-serve runs on a self-managed data plane. Union operates the control plane and installs the data plane through the agent, while the GKE cluster's lifecycle stays with you.
New organizations get $950 in credits for 30 days, whichever runs out first, with no payment method until the end.
The infrastructure is yours. Now the AI factory is too.
If you've already built your AI factory on Google Cloud, Union gives you the production line to run on it: durable runs, accountable compute, and lineage from data to serving, all inside your own project. Watch the Union on Google Cloud walkthrough, read the GCP setup guide, and sign up to connect your first GKE cluster.