Millions of environment steps. None of them lost.
From parallel simulation rollouts to policy updates on multi-node GPUs, Union runs RL training loops with spot-safe checkpointing, reproducibility by design, and cloud-native scaling.
Trusted by leading AI teams





Open source at the core.
Union is built on Flyte, the open-source AI runtime we create and maintain under the Linux Foundation AI & Data.
companies using Flyte today
Flyte SDK downloads
Fan out on durable asyncio.
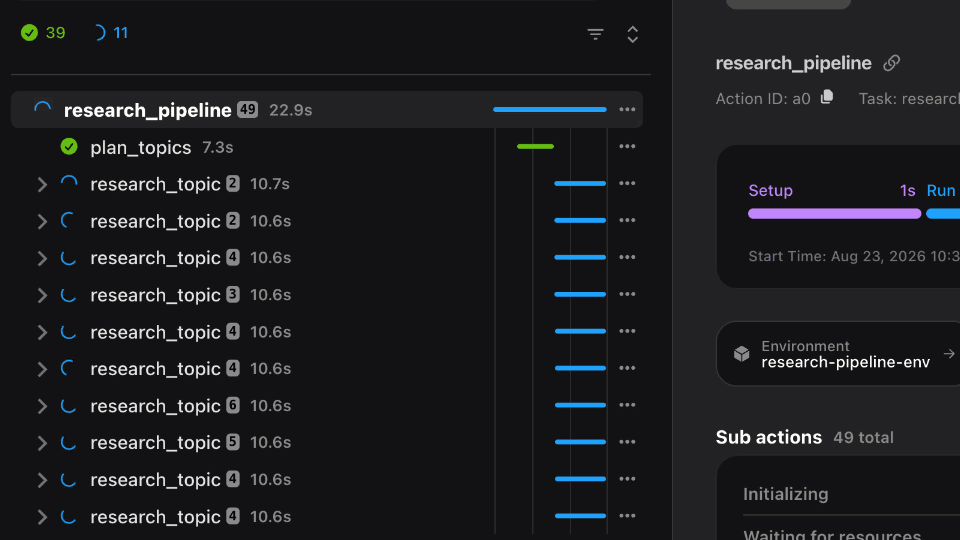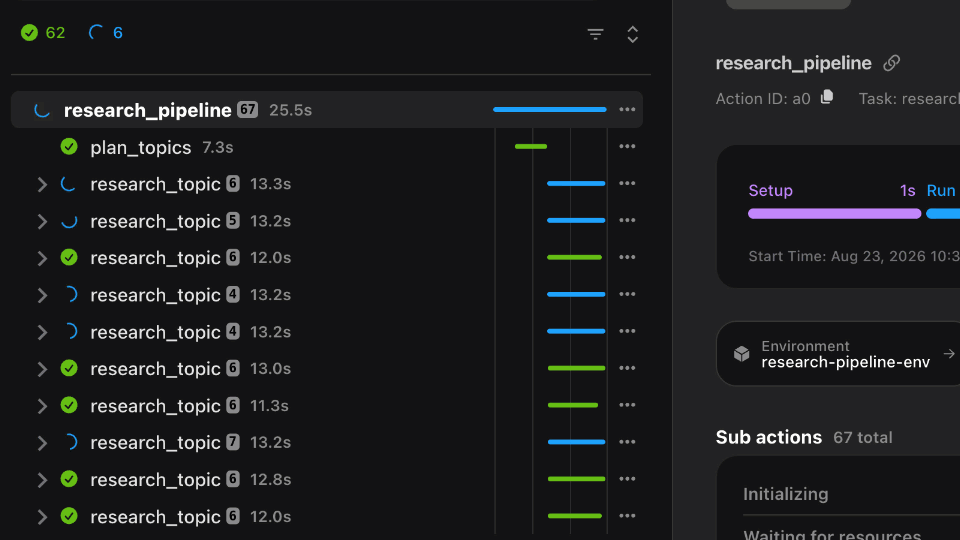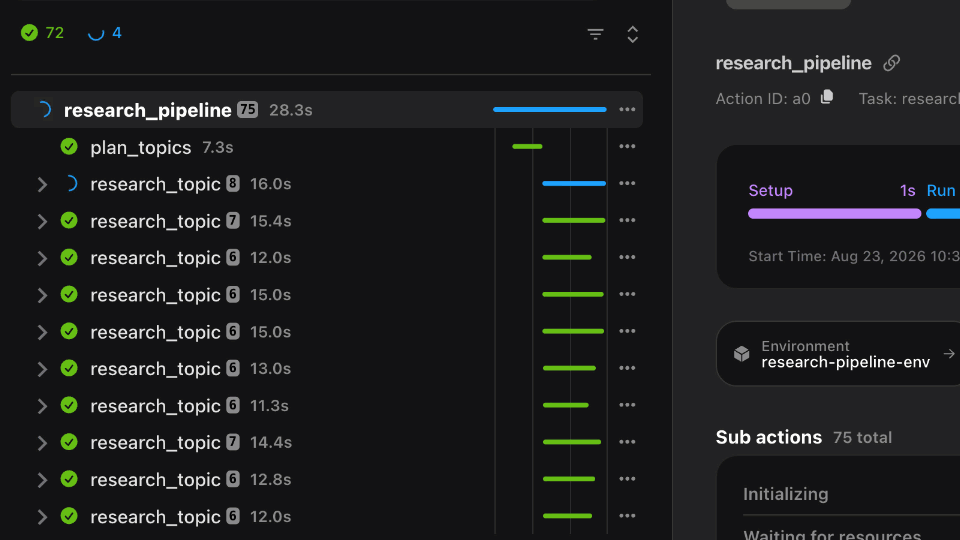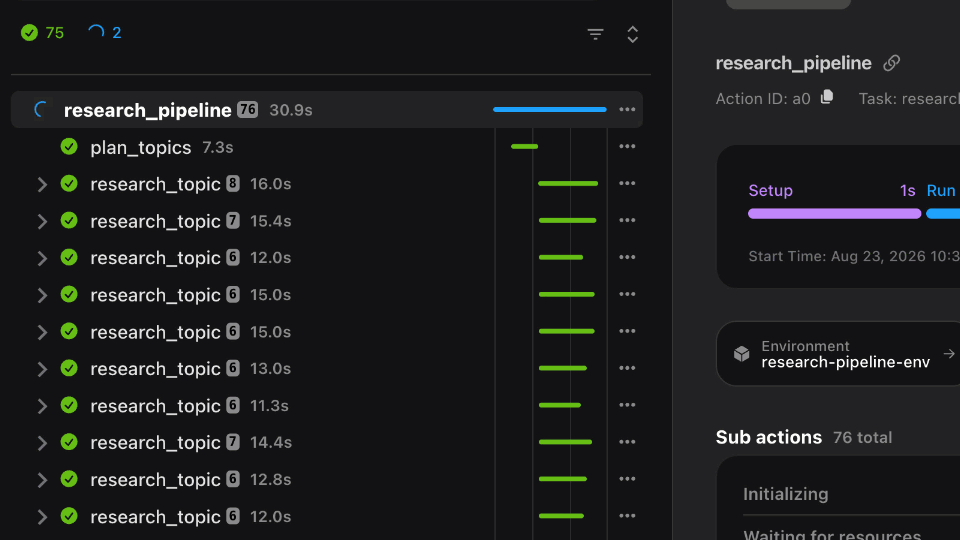
A policy learns as fast as the simulator feeds it. Every iteration wants hundreds of environments stepping at once, and the sampling is CPU work while the update is GPU work. Fanning out over rollouts is plain async, and the cluster scales back to zero between experiments.
- Concurrency you can cap. `flyte.map.aio(fn, seeds, concurrency=256)` bounds how many environments run at once, for a fan-out wider than the cluster.
- CPU sims, GPU learner, one workflow. Each task declares what it needs, so hundreds of cheap simulator containers feed a single expensive GPU step instead of the pipeline sizing everything for its largest node.
- Built for spot. `interruptible=True` puts rollout workers on spot nodes and cuts compute costs by more than 90%. Losing an episode batch is expected here, not an incident.
Recover. Fork. Replay.
Training curves are the one thing you cannot rerun cheaply. A policy that took four days and ten thousand iterations to get interesting is gone if the run dies at iteration nine thousand. Union records what finished as the run happens, outside the node doing the work, and that record is what you resume from.
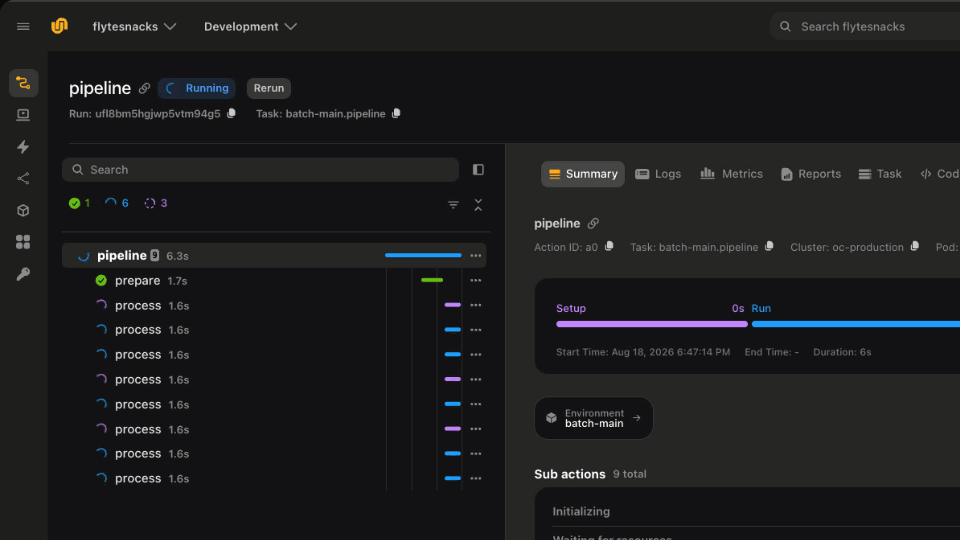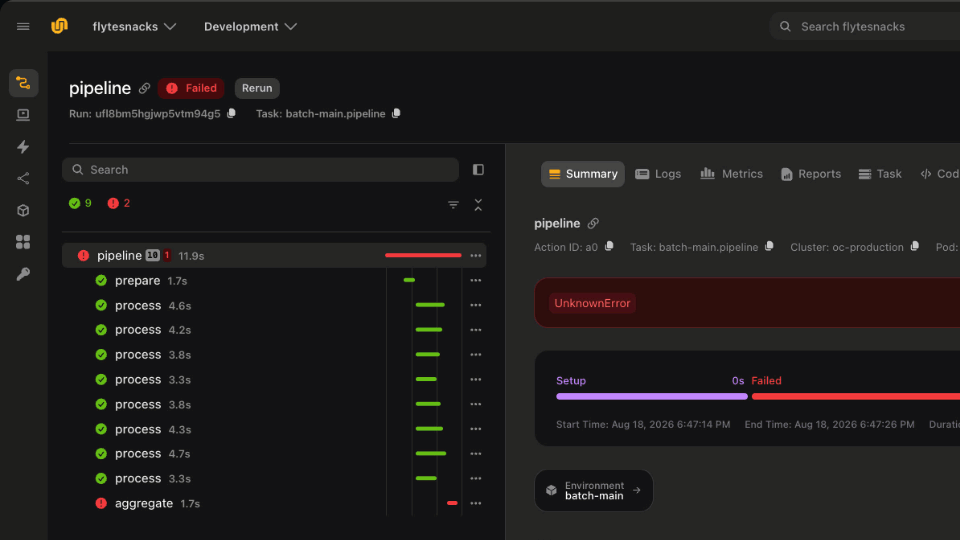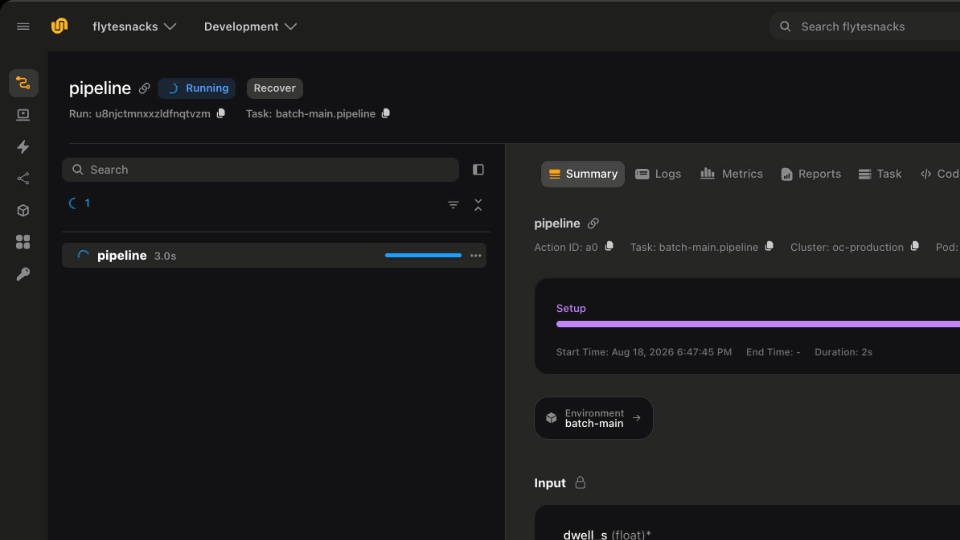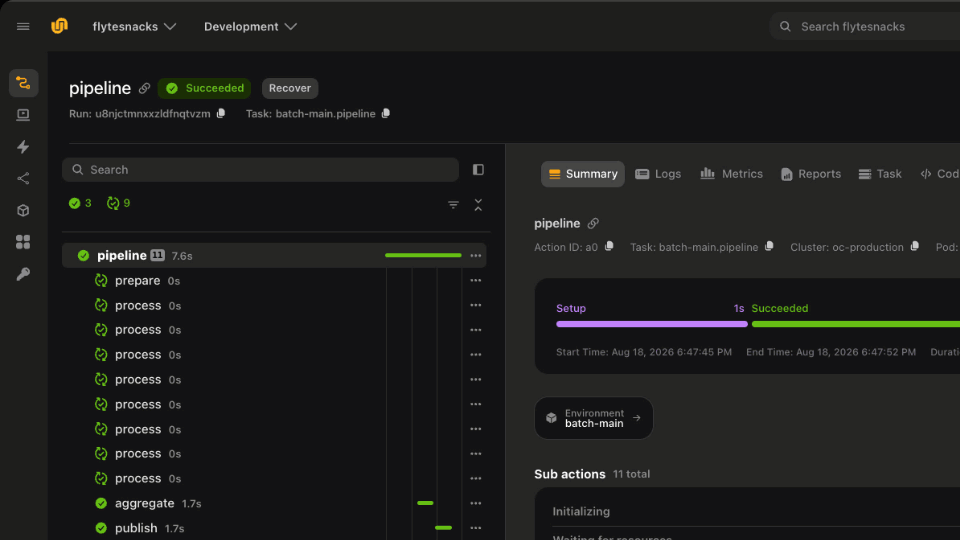
- Recover what failed. Point `recover` at a prior run. Finished iterations are reused and only what failed or changed runs again, even without caching enabled.
- Checkpoints that survive the node. `flyte.Checkpoint` saves policy and optimizer state each iteration, so a preemption resumes at the iteration it stopped rather than at a random initialization.
- Fork a reward function, keep the policy. `flyte.rerun` branches a prior run at the iteration you pick, so a new reward shaping term starts from a trained policy instead of from scratch.
Except blocks can change the hardware.
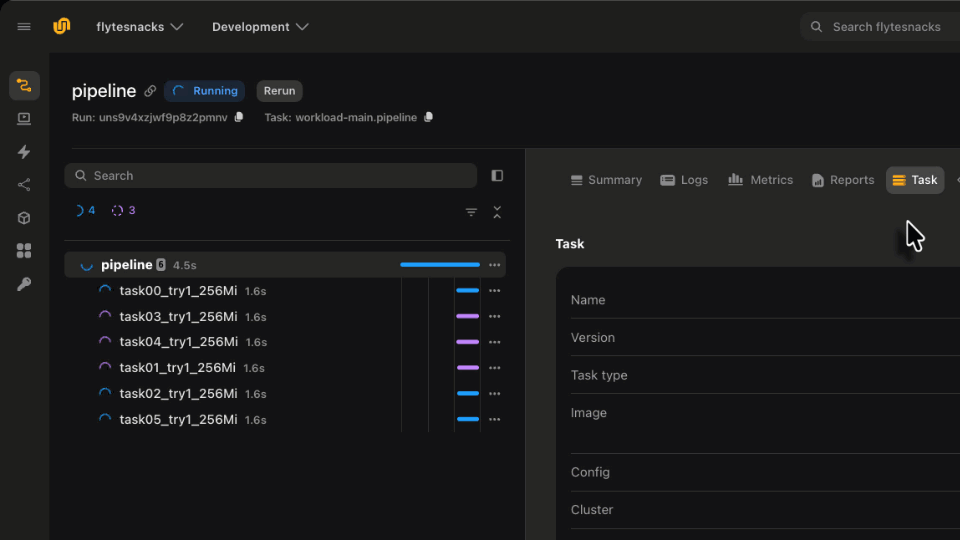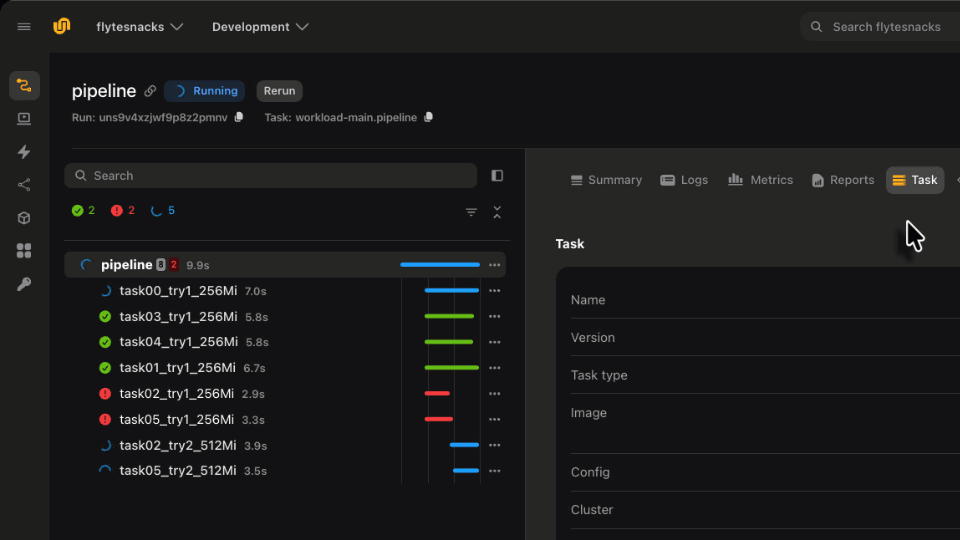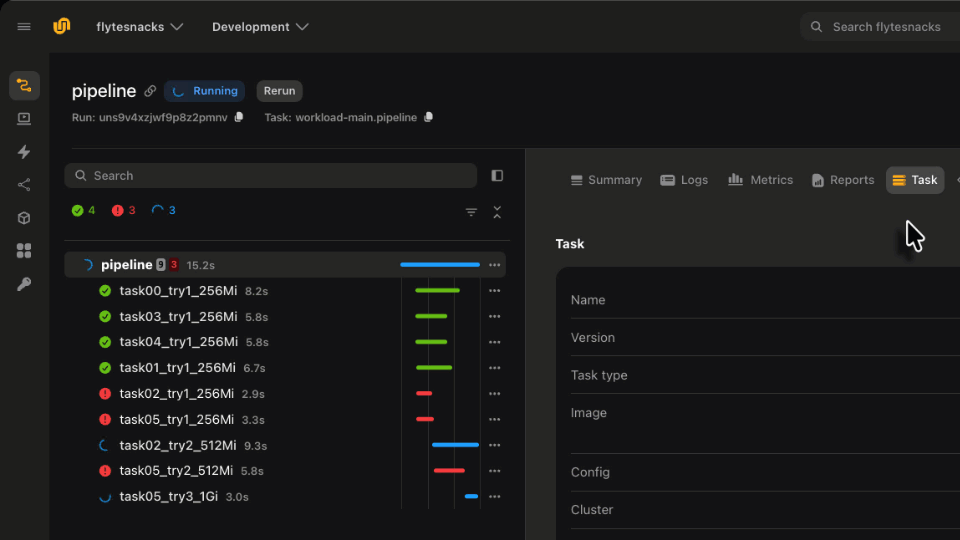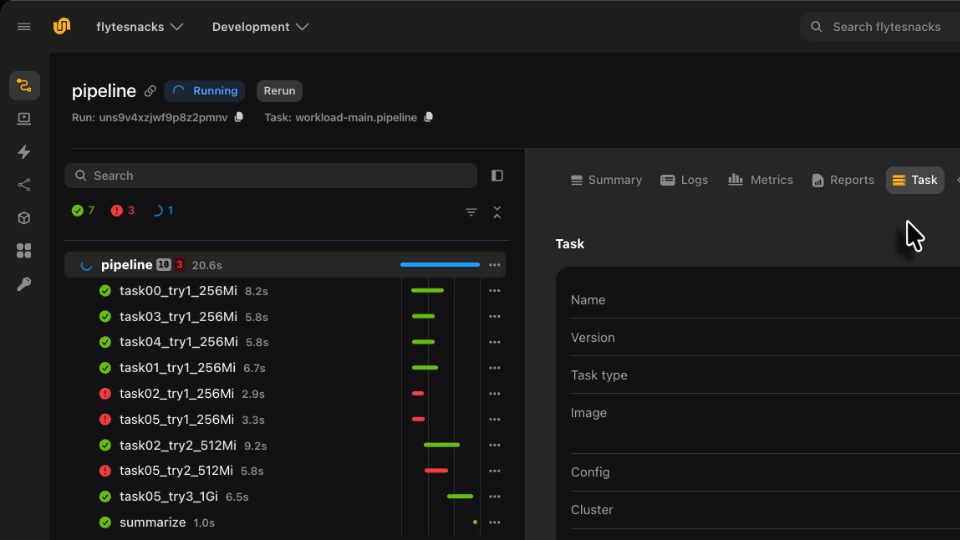
Replay buffers grow until something gives. A buffer sized for a toy control task fits in 8Gi, and the same code on pixel observations with a longer horizon does not. Union hands you a typed error instead of a stack trace, so the step that blows memory comes back as an exception you can catch and re-run on a bigger box.
- Typed infrastructure errors. `OOMError`, `TaskInterruptedError`, `TaskTimeoutError`, `ImagePullBackOffError`. Failures you can branch on.
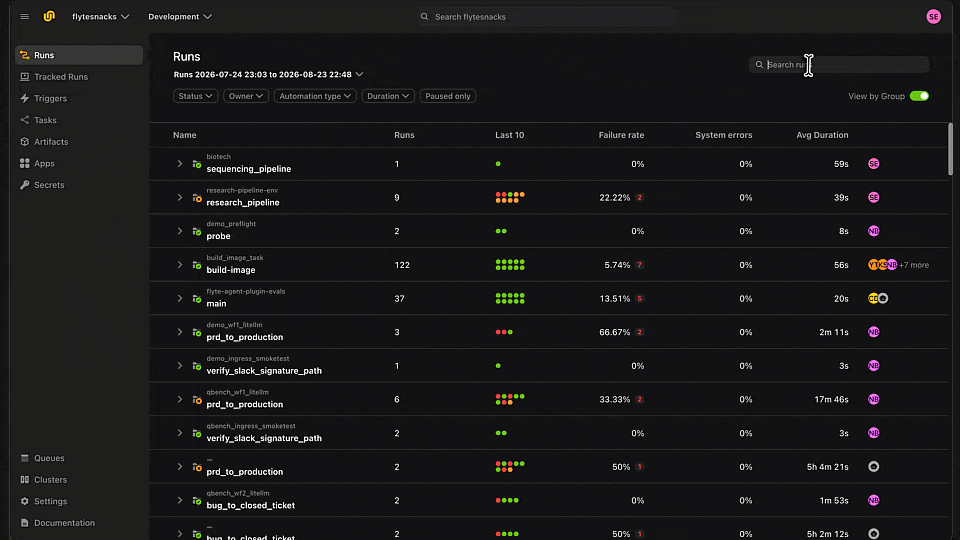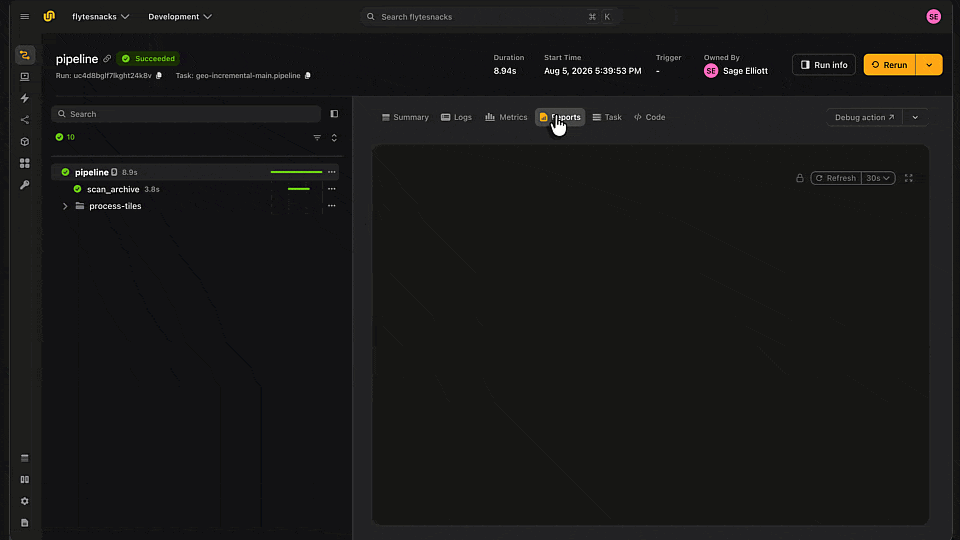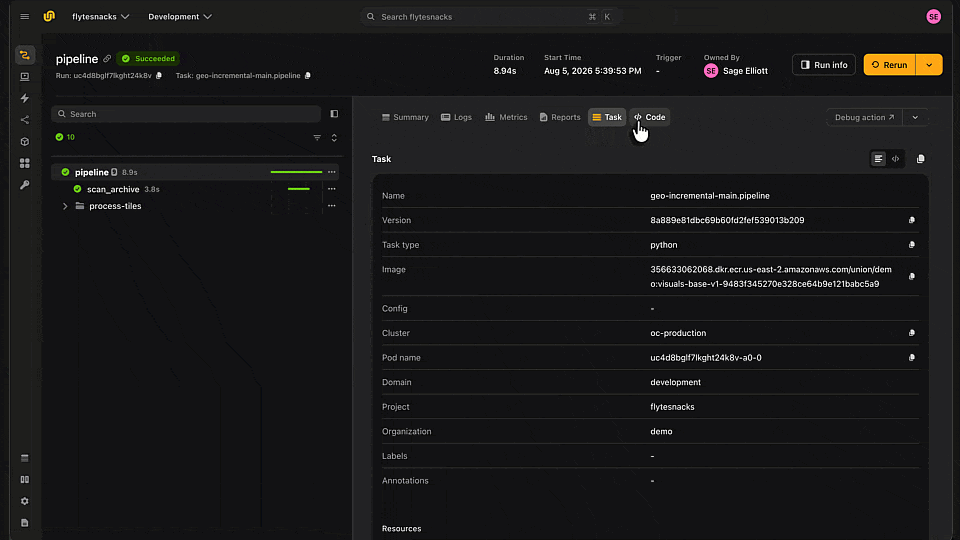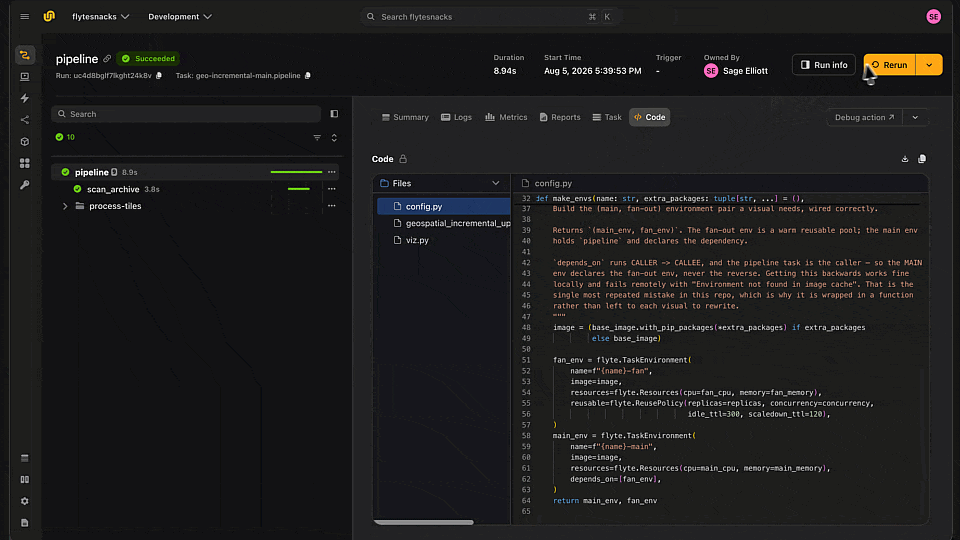
- Resources changed at runtime. `.override(resources=...)` re-runs the same update with more memory, or moves it from an A100 to an H100.
- A hung simulator is a typed error too. `TaskTimeoutError` catches the environment that stopped stepping, so one bad seed does not stall the iteration behind it.
- The handler does not have to be human. Provisioning is an ordinary Python call, so the same API you write a retry policy against is one an agent can call while a run is in flight.
Outputs that outlive the run.
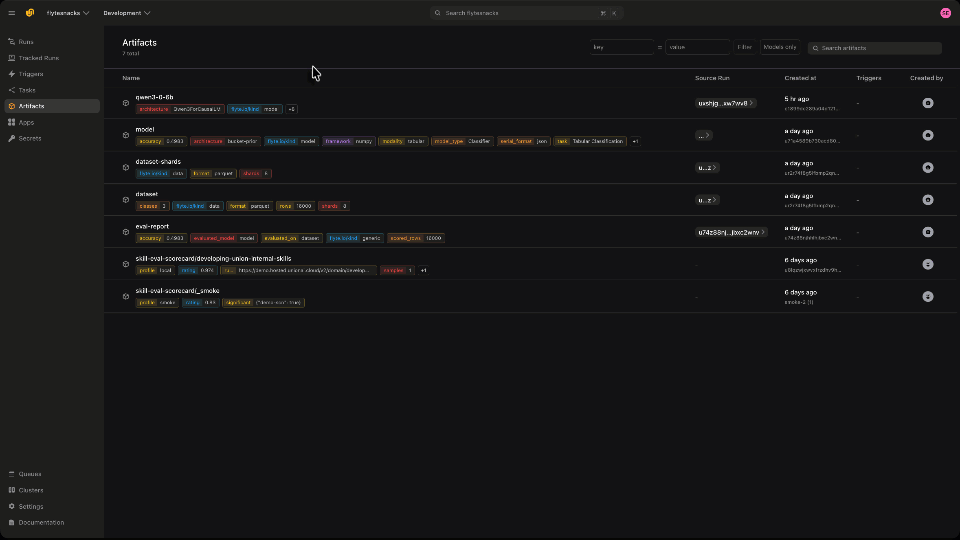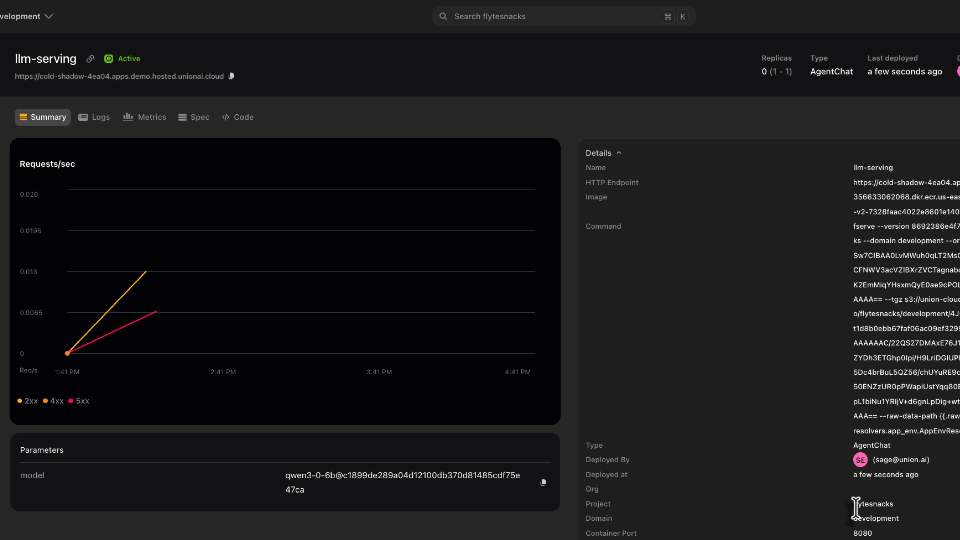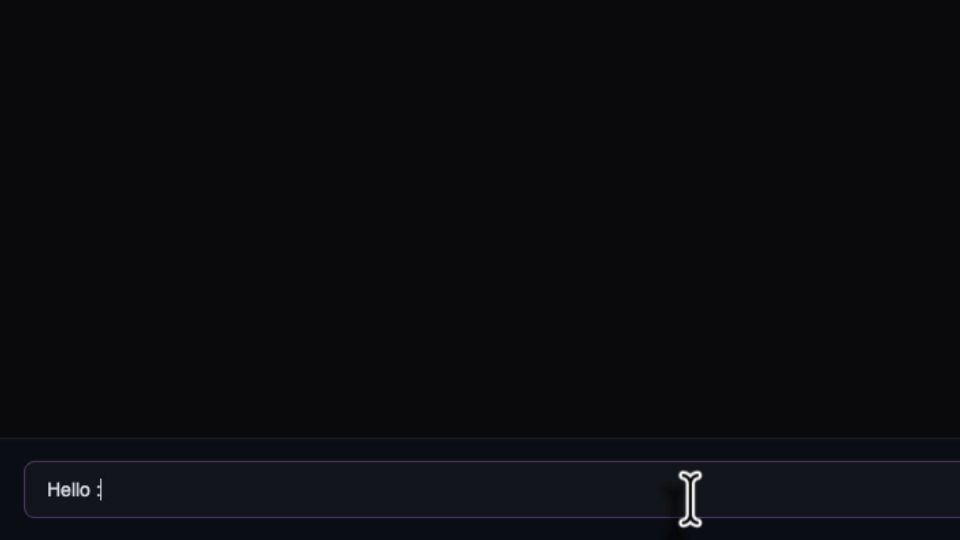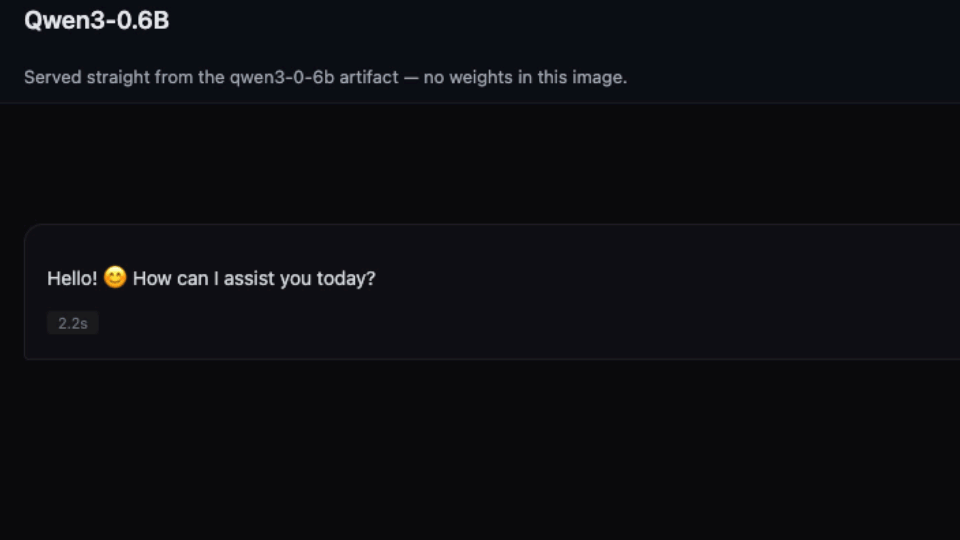
A policy is only useful once something else can load it. Artifacts are typed, versioned values that persist past the run that made them, so an evaluation suite or a sim-to-real deployment picks up a checkpoint without anyone moving weights between buckets, and a promoted policy can trigger the next benchmark by itself.
- Passed between workflows and apps. A training run's policy is an eval workflow's typed input, without re-running the producer.
- Versioned, not overwritten. A new version is a new artifact, so a regression names the exact policy that scored better last week.
- Events, not polling. `flyte.OnArtifact` fires a benchmark whenever a new policy is promoted, with no cron hacks in between.
Reproduce a run from months ago.
RL results are famously hard to reproduce, and the seed is the smallest part of why. Every run keeps what it takes to reproduce a result: the code that executed, the infrastructure it ran on, and the configuration applied to both. That is what makes a training loop shareable rather than personal, and it is what a paper or a postmortem needs.
- Inputs and outputs per run. Open a run from months ago and see the exact reward function, seeds, and environment version behind a policy.
- The code that ran, not the code today. Each run resolves to its own code bundle and container image, down to the simulator build.
- Watch it learn, inside the run. `report.log()` renders reward curves and episode replays in the execution itself, so an experiment documents its own behavior instead of pointing at a dashboard that has since rolled over.
Training loops in pure Python.
Rollouts, updates, checkpoints, and replays, no YAML, no DSLs. Write it in Python, run it across hundreds of workers on Union.
Reinforcement Learning on Union
Tutorials, case studies, and technical deep dives from teams training agents at scale.
Start today and scale with confidence.
Talk to our team about how Union runs simulation, training loops, and evaluation for teams building agents that learn from experience.