AI engineering tip of the week: Agents That Survive a Crash Without Paying for the Same Tokens Twice
A retried task or agent usually starts from scratch. For a batch job that can be annoying. For an AI agent it can be expensive and non-deterministic: you pay for every completed model turn a second time, every tool runs again, and the second attempt may take a different path and give a different answer.
Flyte records the work as it happens, so a retry resumes rather than restarts.
The setup
Nothing special. Tools are tasks with caching, and the agent task has retries:
`durable=True` is the default.
What happens on a crash
Say the worker dies after the agent has called both tools and the model has produced its verdict. Flyte retries the task, and on the second attempt:
Same answer, a fraction of the time, and no repeat billing for work that already succeeded. For example the parent task might show two attempts, while each tool shows exactly one execution, both from the first attempt.
To see it yourself, raise after the agent returns on the first attempt only:
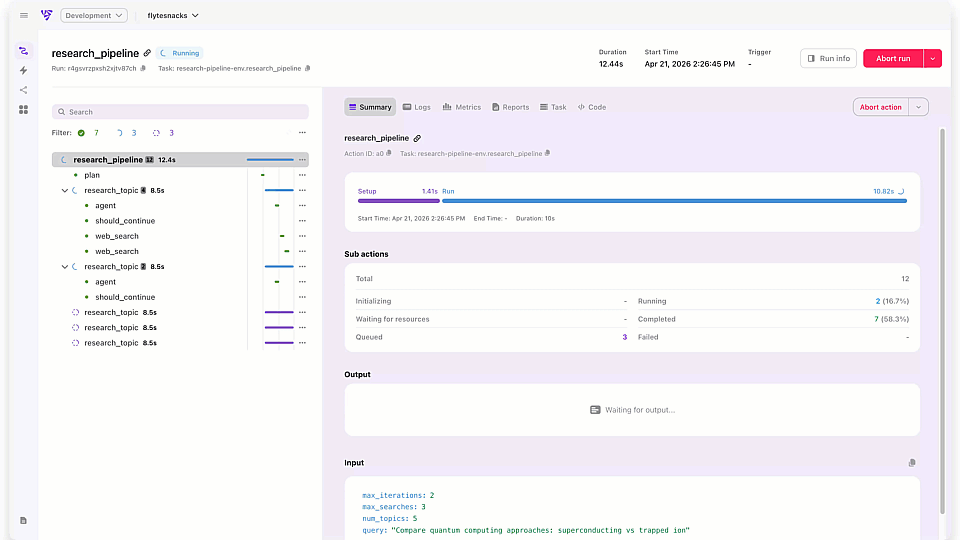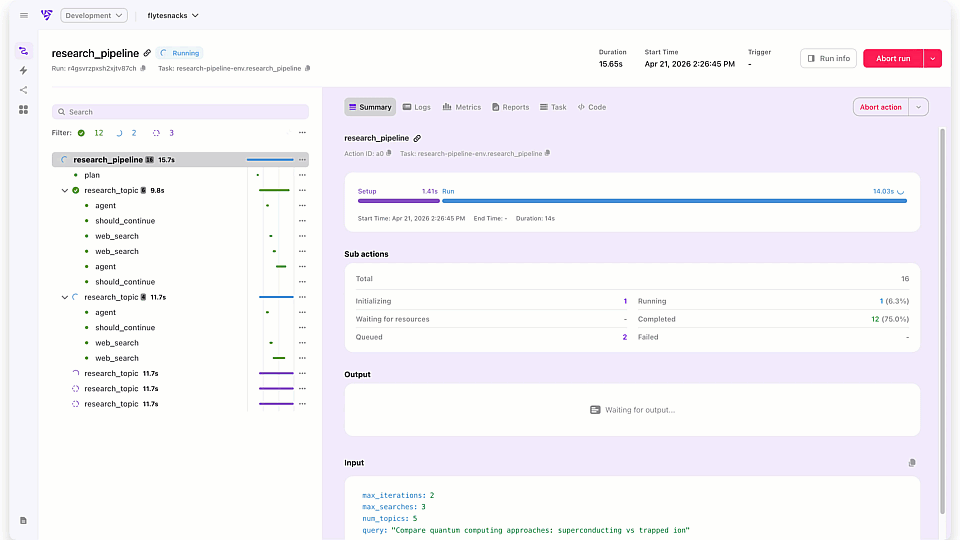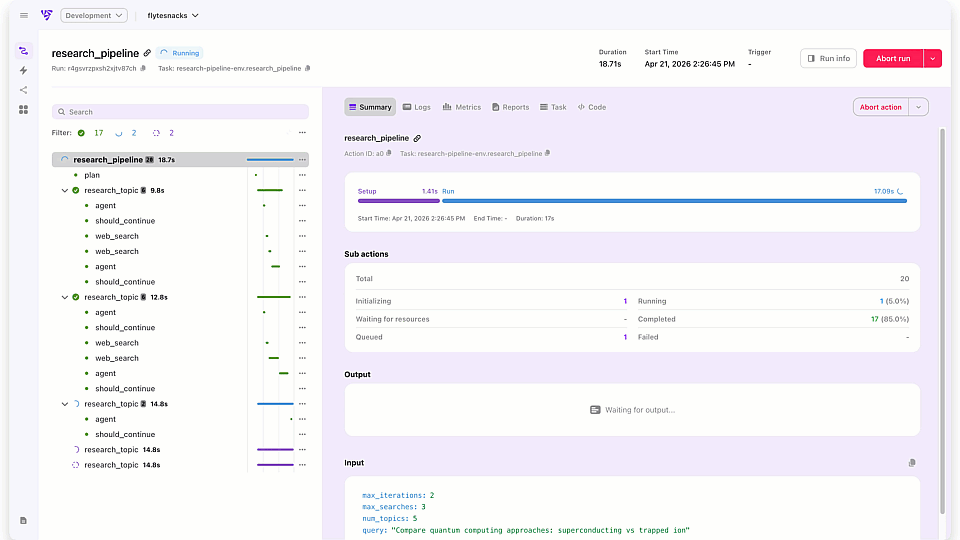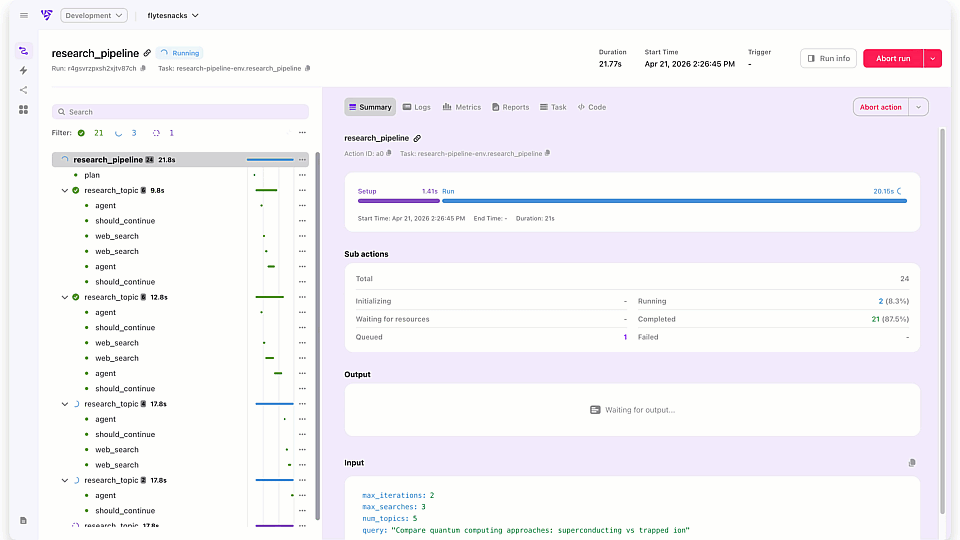
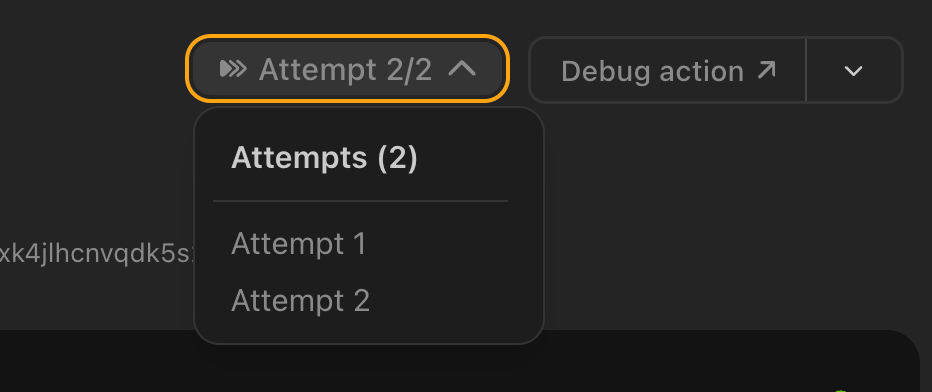
Open the run in the UI and flip the attempt selector. Attempt one shows live tool calls. Attempt two shows a conversation that picked up where it left off, with no new tool executions.
How the two layers work
Tool calls are durable child actions always, regardless of any setting. Each is a Flyte task with its own retries, and `cache="auto"` means identical inputs skip execution. This is ordinary Flyte caching applied to agent tools.
Model turns are where the adapters do the work, and how they do it depends on the framework.
For the OpenAI Agents SDK, LangGraph, Google ADK, and most others, every call to the model is wrapped in a `flyte.trace` and saved with a fingerprint of the request. When the task retries and the agent makes the same call again, Flyte finds the saved result and returns it. No API call, no new tokens. The report shows these turns as cached, so you can see what was replayed and what was fresh.
The Claude Agent SDK is different because its loop runs inside the Claude Code runtime, a separate process Flyte can't see into. So instead of saving each turn, that adapter saves the whole session to a Flyte checkpoint under a session ID that stays the same across attempts. On retry it reopens the session and Claude carries on from the last message. Same result from the outside: the conversation continues instead of starting over.
You don't need a Flyte agent adapter for this
`@flyte.trace` on any function does the same thing. Flyte records the result of each call, keyed by the function, its inputs, and the order it was called in. On retry, a call that matches a record returns the recorded result and never runs. So if you write your own agent loop, put a trace on the function that calls the model and make the tools tasks with `cache="auto"`, and it resumes the same way.
What this is not
Transient model failures like 429s and 5xx are retried in place by the provider's own client, below the durable layer. A turn is only recorded once it has actually succeeded, so you never replay an error.
Why this matters
Full docs: https://www.union.ai/docs/v2/flyte/integrations/agents/how-it-works/
See what's happening in the Flyte Community:
Latest from the blog
- Inside Union: Resource-Aware Scheduling for Flyte 2.0 - Read on Union
- It’s now super easy to start using Union.ai - Read on Union
- Union.ai Launches Self-Service Access on AWS Marketplace to Enable Sovereign AI - Read on Union
- Pandera 0.33: a CLI for validation without writing Python, and native PyArrow table support - Read on Union
- Inside Union: The Replay Log That Makes Flyte 2.0 Durable - Read on Union
- We Ran Multi-Node GRPO on 8 GPUs and the Trainer Cost Us Nothing - Read on Union
Recent talks & recordings
- Union: AI Infrastructure Made Easier - Watch on YouTube
- Flyte 2: The Durable Runtime Built for AI - Watch on YouTube
- When the Pipeline Breaks: Building ML Infrastructure for Biotech R&D | Session 1 - Watch on YouTube
- LLM fine-tuning with GRPO - Watch on YouTube
Upcoming events
- [Seattle] Build Your First Model Factory - Hacknight Seattle | Oct 22nd - RSVP on Luma
- [SF] Own Your AI: Build Your First Model Factory - Hack Night SF | Nov 3 - RSVP on Luma
Releases & updates
- Flyte 2 Is Generally Available: The Durable, Open-Source AI Runtime - Read on Union.ai
<div class="button-group is-center"><a class="button" href="https://www.union.ai/docs/v2/flyte/user-guide/run-modes/running-devbox/">Download Devbox</a></div>
From the community
- AI Book Club: Grokking Deep Reinforcement Learning - RSVP on Luma
That's all for this week! - Sage Elliott